
Should we try it?
\nMany fellow Kagglers are using external datasets, some of them are unlabeled (or labeled for a different task).
\nSelf supervision methods can help capture information from unlabeled datasets.
\n\nAlso: They are a really good \"secret weapon\" to have in your back pocket since if they are implemented in the correct way they can \"just work\" all the time and boost the performance of every model
\n
\n (Like we treat MLM in NLP nowadays because huggingface did all the heavy lifting for us)
Self Supervision Baselines
\nThere had been many self-supervision papers released recently, today we will focus on the following:
\n\n\n\n
\n- Kaggle Notebook
\n- Paper
\n- Official Implementation
\n
A Simple framework for contrastive learning of visual representation
\n
SimCLR provides a great platform (and an easy one too) to help achieve a good representation out of unlabelled images.
\nThe itutions and conjectures provided by the paper comes quite naturally to one's mind. The ease of the concepts will be portrayed in the kernel along with some comments on the same.
SimCLR is based out of the following simplified modules:
\nStochastic Augmentation
\nThe authors suggest that a strong data augmentation is useful for unsupervised learning.
\nThe following augmentation are suggested by the authors:

The data pipeline does not take an image and output a single augmented view, but on the contrary, outputs two randomly augmented views of the original image.
\nThe SimCLR Model
\nThe data pipeline outputs two augmented views of an image. The views go into a neural network encoder 𝑓(.) that gives us the corresponding representation of the augmented views.
Our objective is to maximise the similarity quotient of the two distinct learned representations.
\nThe idea here is to force the model to learn a general representation of an object from two distinct augmented views of it.
\nThe intuition is quite similar to viewing an object from different perspectives and gaining a better understanding.
The authors do not put constraint on the encoder model.
\nContrastive Loss
\nWe use the projected vectors and run cosine similarity function to check how similar they are.
\nWe run the cosine similarity on both the positive and negative pairs. After we have the similarity matrix we apply softmax on to it to get the probability distribution of the entire model.
Our objective is to tune the parameters so that the softmax distribution is peaked on the positive pair.
\nCode: You can find a really good implementation in a Kaggle notebook of SimCLR here
\n\n \n\n
Unsupervised visual representation learning is progressing at an exceptionally fast pace. Most of the modern training frameworks (SimCLR, BYOL, SwAV) in this area make use of a self-supervised model pre-trained with some contrastive learning objective. Saying these frameworks perform great w.r.t supervised model pre-training would be an understatement, as evident from the figure below -
\n
\n
\n
\n
\nThe authors of this paper investigated a question:
\n
\n\nCan we learn a meaningful metric that reflects apparent similarity among instances via pure discriminative learning?
\n
\n
To answer this, they devised a novel unsupervised feature learning algorithm called instance-level discrimination. Here each image and its transformations/views are treated as two separate instances. Each image instance is treated as a separate class. The aim is to learn an embedding, mapping $x$ (image) to $v$ (feature) such that semantically similar instances(images) are closer in the embedding space.
\n
Code: You can find a really good implementation in a Kaggle notebook of SwAV here
\n\n\n\n
\n- Kaggle Notebook
\n- Paper
\n- Official Implementation
\n
Main Idea
\n
BYOL could be summarized in the following 5 straightforward steps.
\nx, two views of the same image v and v are generated by applying two random augmentations to x.v and v to online and target encoders in order, vector representations y'_θ and y'_ϵ are obtained.z_θ and z’_ϵ in the image below.z_θ should predict z’_ϵ and hence another predictor(q_θ) is put on top of z_θ.q_θ(z_θ), z’_ϵ>.Implementation
\nAugmentations
\nTo make oue implementation easy we use the following set of augmentations are used.
\n torchvision transforms tfms\nbyol_tfms = tfms.Compose([\n tfms.RandomResizedCrop(size=, scale=(, )),\n tfms.RandomHorizontalFlip(),\n tfms.ToPILImage(),\n tfms.RandomApply([\n tfms.ColorJitter(, , , )\n ], p=),\n tfms.RandomGrayscale(p=),\n tfms.ToTensor()\n])\nWe then set up a pipeline to run our models through for training with contrastive learning.
\nBelow PyTorch snippet implements the an encoder based BYOL network, but it could also be used in conjunction with any arbitrary encoder network such as VGG, InceptionNet, etc. without any significant change.
BYOL Module
\n (nn.Module):\n ():\n ().__init__()\n self.base_ema = base_target_ema \n backbone :\n backbone = models.resnet50(pretrained=)\n backbone.output_dim = backbone.fc.in_features\n backbone.fc = torch.nn.Identity()\n projector = MLPHead(in_dim=backbone.output_dim) \n self.online_encoder = nn.Sequential(backbone, projector) \n self.target_encoder = copy.deepcopy(self.online_encoder)\n self.online_predictor = MLPHead(in_dim=,hidden_size=, projection_size=) \n\n\n (): \n tau = - (( - self.base_ema)* (cos(pi*global_step/max_steps)+)/) \n online, target (self.online_encoder.parameters(), self.target_encoder.parameters()):\n target.data = tau * target.data + ( - tau) * online.data \n\n (): \n z1 = self.online_encoder(x1)\n z2 = self.online_encoder(x2) \n q1 = self.online_predictor(z1)\n q2 = self.online_predictor(z2) \n torch.no_grad():\n z1_t = self.target_encoder(x1)\n z2_t = self.target_encoder(x2) \n loss = loss_fn(q1, q2, z1_t, z2_t) \n loss\nTraining Loop
\nYou then can use a simple training loop to train your model.
\n epoch global_progress:\n model.train() \n\n idx, (image, label) (local_progress):\n image = image.to(device)\n aug_image = train_transform(image)\n\n model.zero_grad()\n loss = model.forward(image.to(device, non_blocking=), aug_image.to(device, non_blocking=)) \n loss.backward()\n\n optimizer.step()\n model.update_moving_average(epoch, epochs)\n\n scheduler.step() \n \nCode: You can find a good implementation in a Kaggle notebook of BYOL here
", "messages": [ { "id": 2076194, "postDate": "2022-12-26T08:02:41.057Z", "content": "Should we try it?
\nMany fellow Kagglers are using external datasets, some of them are unlabeled (or labeled for a different task).
\nSelf supervision methods can help capture information from unlabeled datasets.
\n\nAlso: They are a really good \"secret weapon\" to have in your back pocket since if they are implemented in the correct way they can \"just work\" all the time and boost the performance of every model
\n
\n (Like we treat MLM in NLP nowadays because huggingface did all the heavy lifting for us)
Self Supervision Baselines
\nThere had been many self-supervision papers released recently, today we will focus on the following:
\n\n\n\n
\n- Kaggle Notebook
\n- Paper
\n- Official Implementation
\n
A Simple framework for contrastive learning of visual representation
\n
SimCLR provides a great platform (and an easy one too) to help achieve a good representation out of unlabelled images.
\nThe itutions and conjectures provided by the paper comes quite naturally to one's mind. The ease of the concepts will be portrayed in the kernel along with some comments on the same.
SimCLR is based out of the following simplified modules:
\nStochastic Augmentation
\nThe authors suggest that a strong data augmentation is useful for unsupervised learning.
\nThe following augmentation are suggested by the authors:
The data pipeline does not take an image and output a single augmented view, but on the contrary, outputs two randomly augmented views of the original image.
\nThe SimCLR Model
\nThe data pipeline outputs two augmented views of an image. The views go into a neural network encoder 𝑓(.) that gives us the corresponding representation of the augmented views.
Our objective is to maximise the similarity quotient of the two distinct learned representations.
\nThe idea here is to force the model to learn a general representation of an object from two distinct augmented views of it.
\nThe intuition is quite similar to viewing an object from different perspectives and gaining a better understanding.
The authors do not put constraint on the encoder model.
\nContrastive Loss
\nWe use the projected vectors and run cosine similarity function to check how similar they are.
\nWe run the cosine similarity on both the positive and negative pairs. After we have the similarity matrix we apply softmax on to it to get the probability distribution of the entire model.
Our objective is to tune the parameters so that the softmax distribution is peaked on the positive pair.
\nCode: You can find a really good implementation in a Kaggle notebook of SimCLR here
\n\n \n\n
Unsupervised visual representation learning is progressing at an exceptionally fast pace. Most of the modern training frameworks (SimCLR, BYOL, SwAV) in this area make use of a self-supervised model pre-trained with some contrastive learning objective. Saying these frameworks perform great w.r.t supervised model pre-training would be an understatement, as evident from the figure below -
\n
\n
\n
\n
\nThe authors of this paper investigated a question:
\n
\n\nCan we learn a meaningful metric that reflects apparent similarity among instances via pure discriminative learning?
\n
\n
To answer this, they devised a novel unsupervised feature learning algorithm called instance-level discrimination. Here each image and its transformations/views are treated as two separate instances. Each image instance is treated as a separate class. The aim is to learn an embedding, mapping $x$ (image) to $v$ (feature) such that semantically similar instances(images) are closer in the embedding space.
\n
Code: You can find a really good implementation in a Kaggle notebook of SwAV here
\n\n\n\n
\n- Kaggle Notebook
\n- Paper
\n- Official Implementation
\n
Main Idea
\n
BYOL could be summarized in the following 5 straightforward steps.
\nx, two views of the same image v and v are generated by applying two random augmentations to x.v and v to online and target encoders in order, vector representations y'_θ and y'_ϵ are obtained.z_θ and z’_ϵ in the image below.z_θ should predict z’_ϵ and hence another predictor(q_θ) is put on top of z_θ.q_θ(z_θ), z’_ϵ>.Implementation
\nAugmentations
\nTo make oue implementation easy we use the following set of augmentations are used.
\n torchvision transforms tfms\nbyol_tfms = tfms.Compose([\n tfms.RandomResizedCrop(size=, scale=(, )),\n tfms.RandomHorizontalFlip(),\n tfms.ToPILImage(),\n tfms.RandomApply([\n tfms.ColorJitter(, , , )\n ], p=),\n tfms.RandomGrayscale(p=),\n tfms.ToTensor()\n])\nWe then set up a pipeline to run our models through for training with contrastive learning.
\nBelow PyTorch snippet implements the an encoder based BYOL network, but it could also be used in conjunction with any arbitrary encoder network such as VGG, InceptionNet, etc. without any significant change.
BYOL Module
\n (nn.Module):\n ():\n ().__init__()\n self.base_ema = base_target_ema \n backbone :\n backbone = models.resnet50(pretrained=)\n backbone.output_dim = backbone.fc.in_features\n backbone.fc = torch.nn.Identity()\n projector = MLPHead(in_dim=backbone.output_dim) \n self.online_encoder = nn.Sequential(backbone, projector) \n self.target_encoder = copy.deepcopy(self.online_encoder)\n self.online_predictor = MLPHead(in_dim=,hidden_size=, projection_size=) \n\n\n (): \n tau = - (( - self.base_ema)* (cos(pi*global_step/max_steps)+)/) \n online, target (self.online_encoder.parameters(), self.target_encoder.parameters()):\n target.data = tau * target.data + ( - tau) * online.data \n\n (): \n z1 = self.online_encoder(x1)\n z2 = self.online_encoder(x2) \n q1 = self.online_predictor(z1)\n q2 = self.online_predictor(z2) \n torch.no_grad():\n z1_t = self.target_encoder(x1)\n z2_t = self.target_encoder(x2) \n loss = loss_fn(q1, q2, z1_t, z2_t) \n loss\nTraining Loop
\nYou then can use a simple training loop to train your model.
\n epoch global_progress:\n model.train() \n\n idx, (image, label) (local_progress):\n image = image.to(device)\n aug_image = train_transform(image)\n\n model.zero_grad()\n loss = model.forward(image.to(device, non_blocking=), aug_image.to(device, non_blocking=)) \n loss.backward()\n\n optimizer.step()\n model.update_moving_average(epoch, epochs)\n\n scheduler.step() \n \nCode: You can find a good implementation in a Kaggle notebook of BYOL here
", "rawMarkdown": "#### Self-supervision\n**Should we try it?**\n\nMany fellow Kagglers are using external datasets, some of them are unlabeled (or labeled for a different task).\nSelf supervision methods can help capture information from unlabeled datasets. \n\n> **Also:** They are a really good \"secret weapon\" to have in your back pocket since if they are implemented in the correct way they can \"just work\" all the time and boost the performance of every model \n> **(Like we treat MLM in NLP nowadays because huggingface did all the heavy lifting for us)**\n\n\n_____\n\n\n**Self Supervision Baselines**\n\nThere had been many self-supervision papers released recently, today we will focus on the following: \n\n- **BYOL:** [Bootstrap Your Own Latent](https://arxiv.org/abs/2006.07733) - \n- **SwAV:** [Unsupervised Learning of Visual Features by Contrasting Cluster Assignments](https://arxiv.org/abs/2006.09882)\n- **SimCLR:** [A Simple Framework for Contrastive Learning of Visual Representations](https://arxiv.org/abs/2002.05709)\n\n_____\n\n\n### SimCLR\n##### A Simple Framework for Contrastive Learning of Visual Representations\n\n> - [Kaggle Notebook](https://www.kaggle.com/code/aritrag/simclr)\n> - [Paper](https://arxiv.org/abs/2002.05709)\n> - [Official Implementation](https://github.com/google-research/simclr)\n\nA Simple framework for contrastive learning of visual representation\n\n\n\n\nSimCLR provides a great platform (and an easy one too) to help achieve a good representation out of unlabelled images. \nThe itutions and conjectures provided by the paper comes quite naturally to one's mind. The ease of the concepts will be portrayed in the kernel along with some comments on the same.\n\n\n**SimCLR is based out of the following simplified modules:**\n\n- A stochastic data augmentation module.\n- A neural network base encoder 𝑓(.) .\n- A neural network projection head 𝑔(.) \n- A contrastive loss function.\n\n**Stochastic Augmentation**\n\nThe authors suggest that a strong data augmentation is useful for unsupervised learning. \nThe following augmentation are suggested by the authors:\n\n- Random Crop with Resize\n- Random Horizontal Flip with 50% probability\n- Random Color Distortion\n- Random Color Jitter with 80% probability\n- Random Color Drop with 20% probability\n- Random Gaussian Blur with 50% probability\n\n\n\n\n\nThe data pipeline does not take an image and output a single augmented view, but on the contrary, outputs two randomly augmented views of the original image.\n\n**The SimCLR Model**\nThe data pipeline outputs two augmented views of an image. The views go into a neural network encoder 𝑓(.) that gives us the corresponding representation of the augmented views.\n\n**Our objective is to maximise the similarity quotient of the two distinct learned representations.**\n\nThe idea here is to force the model to learn a general representation of an object from two distinct augmented views of it.\nThe intuition is quite similar to viewing an object from different perspectives and gaining a better understanding.\n\nThe authors **do not put constraint** on the encoder model. \n\n\n**Contrastive Loss**\n\nWe use the projected vectors and run cosine similarity function to check how similar they are.\nWe run the cosine similarity on both the positive and negative pairs. After we have the similarity matrix we apply softmax on to it to get the probability distribution of the entire model.\n\n**Our objective is** to tune the parameters so that the softmax distribution is peaked on the positive pair.\n\n\n**Code:** You can find a really good implementation in a Kaggle notebook of SimCLR [here](https://www.kaggle.com/code/aritrag/simclr)\n\n\n_____\n\n\n\n### SwAV\n##### Unsupervised Learning of Visual Features by Contrasting Cluster Assignments\n\n> - [Kaggle Notebook](https://www.kaggle.com/code/ayuraj/v2-self-supervised-pretraining-with-swav/notebook)\n> - [Paper](https://arxiv.org/abs/2006.09882) \n> - [PyTorch Implementation](https://github.com/facebookresearch/swav)\n> - [TensorFlow Implementation](https://github.com/ayulockin/SwAV-TF)\n\n\nUnsupervised visual representation learning is progressing at an exceptionally fast pace. Most of the modern training frameworks (SimCLR, BYOL, SwAV) in this area make use of a self-supervised model pre-trained with some contrastive learning objective. Saying these frameworks perform great w.r.t supervised model pre-training would be an understatement, as evident from the figure below -\n## How can SwAV be helpful in this competition?\n\n\n## What's SwAV?\n\n\n\nThe authors of this paper investigated a question:\n\n\n> **Can we learn a meaningful metric that reflects apparent similarity among instances via pure discriminative learning?**\n\n\n\nTo answer this, they devised a novel unsupervised feature learning algorithm called instance-level discrimination. Here each image and its transformations/views are treated as two separate instances. Each image instance is treated as a separate class. The aim is to learn an embedding, mapping $x$ (image) to $v$ (feature) such that semantically similar instances(images) are closer in the embedding space.\n\n\n**Code:** You can find a really good implementation in a Kaggle notebook of SwAV [here](https://www.kaggle.com/code/ayuraj/v2-self-supervised-pretraining-with-swav/notebook)\n\n\n_____\n\n\n\n### BYOL\n##### Bootstrap Your Own Latent\n\n> - [Kaggle Notebook](https://www.kaggle.com/code/nikhilpandey360/contrastive-learning-using-byol)\n> - [Paper](https://arxiv.org/abs/2006.07733)\n> - [Official Implementation](https://github.com/lucidrains/byol-pytorch)\n\n\n**Main Idea**\n\n\n\n\n\nBYOL could be summarized in the following 5 straightforward steps.\n\n- Given an input image `x`, two views of the same image `v` and `v` are generated by applying two random augmentations to `x`.\n- Given `v` and `v` to online and target encoders in order, vector representations `y'_θ` and `y'_ϵ` are obtained.\n- Now, these representations are projected to another subspace z. These projected representations are indicated by `z_θ` and `z’_ϵ` in the image below.\n- Since the target network is the slow moving average of the online network, the online representations should be predictive of the target representations, i.e. `z_θ` should predict `z’_ϵ` and hence another predictor(`q_θ`) is put on top of `z_θ`.\n- Contrastive loss is reduced between <`q_θ(z_θ)`, `z’_ϵ`>.\n\n\n**Implementation**\n\n**Augmentations**\n\nTo make oue implementation easy we use the following set of augmentations are used.\n\n```python\nfrom torchvision import transforms as tfms\nbyol_tfms = tfms.Compose([\n tfms.RandomResizedCrop(size=512, scale=(0.3, 1)),\n tfms.RandomHorizontalFlip(),\n tfms.ToPILImage(),\n tfms.RandomApply([\n tfms.ColorJitter(0.4, 0.4, 0.4, 0.1)\n ], p=0.8),\n tfms.RandomGrayscale(p=0.2),\n tfms.ToTensor()\n])\n```\n\nWe then set up a pipeline to run our models through for training with contrastive learning. \nBelow PyTorch snippet implements the an encoder based BYOL network, but it could also be used in conjunction with any arbitrary encoder network such as VGG, InceptionNet, etc. without any significant change.\n\n**BYOL Module**\n\n\n```python\nclass BYOL(nn.Module):\n def __init__(self, backbone=None,base_target_ema=0.996,**kwargs):\n super().__init__()\n self.base_ema = base_target_ema \n if backbone is None:\n backbone = models.resnet50(pretrained=False)\n backbone.output_dim = backbone.fc.in_features\n backbone.fc = torch.nn.Identity()\n projector = MLPHead(in_dim=backbone.output_dim) \n self.online_encoder = nn.Sequential(backbone, projector) \n self.target_encoder = copy.deepcopy(self.online_encoder)\n self.online_predictor = MLPHead(in_dim=256,hidden_size=1024, projection_size=256) \n\n @torch.no_grad()\n def update_moving_average(self, global_step, max_steps): \n tau = 1- ((1 - self.base_ema)* (cos(pi*global_step/max_steps)+1)/2) \n for online, target in zip(self.online_encoder.parameters(), self.target_encoder.parameters()):\n target.data = tau * target.data + (1 - tau) * online.data \n \n def forward(self,x1,x2): \n z1 = self.online_encoder(x1)\n z2 = self.online_encoder(x2) \n q1 = self.online_predictor(z1)\n q2 = self.online_predictor(z2) \n with torch.no_grad():\n z1_t = self.target_encoder(x1)\n z2_t = self.target_encoder(x2) \n loss = loss_fn(q1, q2, z1_t, z2_t) \n return loss\n```\n\n\n**Training Loop**\n\nYou then can use a simple training loop to train your model.\n\n\n```python\nfor epoch in global_progress:\n model.train() \n \n for idx, (image, label) in enumerate(local_progress):\n image = image.to(device)\n aug_image = train_transform(image)\n \n model.zero_grad()\n loss = model.forward(image.to(device, non_blocking=True), aug_image.to(device, non_blocking=True)) \n loss.backward()\n \n optimizer.step()\n model.update_moving_average(epoch, epochs)\n \n scheduler.step() \n``` \n\n\n\n**Code:** You can find a good implementation in a Kaggle notebook of BYOL [here](https://www.kaggle.com/code/nikhilpandey360/contrastive-learning-using-byol)", "votes": 12 }, { "id": 2079078, "postDate": "2022-12-29T00:43:45.987Z", "content": "Self-Supervised Deep Learning to Enhance Breast Cancer Detection on Screening Mammograph
\nhttps://arxiv.org/pdf/2203.08812.pdf

\n
fyi:
\nA built in MIP (multiple instance pooling) network is facebook's PatchConvnet[1]
\n\" We replace the final average pooling by an attention-based aggregation layer akin to a single transformer block, that weights how the patches are involved in the classification decision.\"
\n[1] Augmenting Convolutional networks with attention-based aggregation
\n[2] https://github.com/facebookresearch/deit/blob/main/README_patchconvnet.md

\n\n\n---\n\nfyi:\n\nA built in MIP (multiple instance pooling) network is facebook's PatchConvnet[1]\n\n\" We replace the final average pooling by an attention-based aggregation layer akin to a single transformer block, that weights how the patches are involved in the classification decision.\"\n\n[1] Augmenting Convolutional networks with attention-based aggregation \n[2] https://github.com/facebookresearch/deit/blob/main/README_patchconvnet.md\n\n\n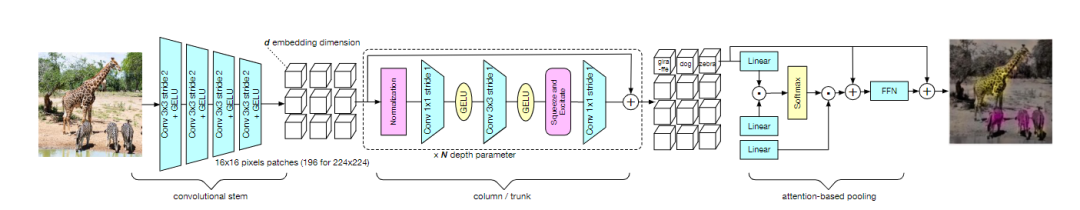",
"votes": 3
},
{
"id": 2076861,
"postDate": "2022-12-27T00:02:27.693Z",
"content": "Great thread! I also feel self-supervision is very much worth exploring in this competition.
\nThe dataset is unbalanced, there are not that many examples in total and we are using models that have been pretrained on Imagenet, images that are vastly different from the DICOMs we get to work with in this competition.
\nReally nice write-up of the available techniques!
", "rawMarkdown": "Great thread! I also feel self-supervision is very much worth exploring in this competition.\n\nThe dataset is unbalanced, there are not that many examples in total and we are using models that have been pretrained on Imagenet, images that are vastly different from the DICOMs we get to work with in this competition.\n\nReally nice write-up of the available techniques!", "votes": 1 } ], "comments": [ { "id": 2079078, "author_name": "hengck23", "author_url": "", "post_date": "2022-12-29T00:43:45.987000", "content": "Self-Supervised Deep Learning to Enhance Breast Cancer Detection on Screening Mammograph
\nhttps://arxiv.org/pdf/2203.08812.pdf
\n
fyi:
\nA built in MIP (multiple instance pooling) network is facebook's PatchConvnet[1]
\n\" We replace the final average pooling by an attention-based aggregation layer akin to a single transformer block, that weights how the patches are involved in the classification decision.\"
\n[1] Augmenting Convolutional networks with attention-based aggregation
\n[2] https://github.com/facebookresearch/deit/blob/main/README_patchconvnet.md
Great thread! I also feel self-supervision is very much worth exploring in this competition.
\nThe dataset is unbalanced, there are not that many examples in total and we are using models that have been pretrained on Imagenet, images that are vastly different from the DICOMs we get to work with in this competition.
\nReally nice write-up of the available techniques!
", "votes": 1, "replies": [] } ], "raw_markdown_by_id": { "2076194": "#### Self-supervision\n**Should we try it?**\n\nMany fellow Kagglers are using external datasets, some of them are unlabeled (or labeled for a different task).\nSelf supervision methods can help capture information from unlabeled datasets. \n\n> **Also:** They are a really good \"secret weapon\" to have in your back pocket since if they are implemented in the correct way they can \"just work\" all the time and boost the performance of every model \n> **(Like we treat MLM in NLP nowadays because huggingface did all the heavy lifting for us)**\n\n\n_____\n\n\n**Self Supervision Baselines**\n\nThere had been many self-supervision papers released recently, today we will focus on the following: \n\n- **BYOL:** [Bootstrap Your Own Latent](https://arxiv.org/abs/2006.07733) - \n- **SwAV:** [Unsupervised Learning of Visual Features by Contrasting Cluster Assignments](https://arxiv.org/abs/2006.09882)\n- **SimCLR:** [A Simple Framework for Contrastive Learning of Visual Representations](https://arxiv.org/abs/2002.05709)\n\n_____\n\n\n### SimCLR\n##### A Simple Framework for Contrastive Learning of Visual Representations\n\n> - [Kaggle Notebook](https://www.kaggle.com/code/aritrag/simclr)\n> - [Paper](https://arxiv.org/abs/2002.05709)\n> - [Official Implementation](https://github.com/google-research/simclr)\n\nA Simple framework for contrastive learning of visual representation\n\n\n\n\nSimCLR provides a great platform (and an easy one too) to help achieve a good representation out of unlabelled images. \nThe itutions and conjectures provided by the paper comes quite naturally to one's mind. The ease of the concepts will be portrayed in the kernel along with some comments on the same.\n\n\n**SimCLR is based out of the following simplified modules:**\n\n- A stochastic data augmentation module.\n- A neural network base encoder 𝑓(.) .\n- A neural network projection head 𝑔(.) \n- A contrastive loss function.\n\n**Stochastic Augmentation**\n\nThe authors suggest that a strong data augmentation is useful for unsupervised learning. \nThe following augmentation are suggested by the authors:\n\n- Random Crop with Resize\n- Random Horizontal Flip with 50% probability\n- Random Color Distortion\n- Random Color Jitter with 80% probability\n- Random Color Drop with 20% probability\n- Random Gaussian Blur with 50% probability\n\n\n\n\n\nThe data pipeline does not take an image and output a single augmented view, but on the contrary, outputs two randomly augmented views of the original image.\n\n**The SimCLR Model**\nThe data pipeline outputs two augmented views of an image. The views go into a neural network encoder 𝑓(.) that gives us the corresponding representation of the augmented views.\n\n**Our objective is to maximise the similarity quotient of the two distinct learned representations.**\n\nThe idea here is to force the model to learn a general representation of an object from two distinct augmented views of it.\nThe intuition is quite similar to viewing an object from different perspectives and gaining a better understanding.\n\nThe authors **do not put constraint** on the encoder model. \n\n\n**Contrastive Loss**\n\nWe use the projected vectors and run cosine similarity function to check how similar they are.\nWe run the cosine similarity on both the positive and negative pairs. After we have the similarity matrix we apply softmax on to it to get the probability distribution of the entire model.\n\n**Our objective is** to tune the parameters so that the softmax distribution is peaked on the positive pair.\n\n\n**Code:** You can find a really good implementation in a Kaggle notebook of SimCLR [here](https://www.kaggle.com/code/aritrag/simclr)\n\n\n_____\n\n\n\n### SwAV\n##### Unsupervised Learning of Visual Features by Contrasting Cluster Assignments\n\n> - [Kaggle Notebook](https://www.kaggle.com/code/ayuraj/v2-self-supervised-pretraining-with-swav/notebook)\n> - [Paper](https://arxiv.org/abs/2006.09882) \n> - [PyTorch Implementation](https://github.com/facebookresearch/swav)\n> - [TensorFlow Implementation](https://github.com/ayulockin/SwAV-TF)\n\n\nUnsupervised visual representation learning is progressing at an exceptionally fast pace. Most of the modern training frameworks (SimCLR, BYOL, SwAV) in this area make use of a self-supervised model pre-trained with some contrastive learning objective. Saying these frameworks perform great w.r.t supervised model pre-training would be an understatement, as evident from the figure below -\n## How can SwAV be helpful in this competition?\n\n\n## What's SwAV?\n\n\n\nThe authors of this paper investigated a question:\n\n\n> **Can we learn a meaningful metric that reflects apparent similarity among instances via pure discriminative learning?**\n\n\n\nTo answer this, they devised a novel unsupervised feature learning algorithm called instance-level discrimination. Here each image and its transformations/views are treated as two separate instances. Each image instance is treated as a separate class. The aim is to learn an embedding, mapping $x$ (image) to $v$ (feature) such that semantically similar instances(images) are closer in the embedding space.\n\n\n**Code:** You can find a really good implementation in a Kaggle notebook of SwAV [here](https://www.kaggle.com/code/ayuraj/v2-self-supervised-pretraining-with-swav/notebook)\n\n\n_____\n\n\n\n### BYOL\n##### Bootstrap Your Own Latent\n\n> - [Kaggle Notebook](https://www.kaggle.com/code/nikhilpandey360/contrastive-learning-using-byol)\n> - [Paper](https://arxiv.org/abs/2006.07733)\n> - [Official Implementation](https://github.com/lucidrains/byol-pytorch)\n\n\n**Main Idea**\n\n\n\n\n\nBYOL could be summarized in the following 5 straightforward steps.\n\n- Given an input image `x`, two views of the same image `v` and `v` are generated by applying two random augmentations to `x`.\n- Given `v` and `v` to online and target encoders in order, vector representations `y'_θ` and `y'_ϵ` are obtained.\n- Now, these representations are projected to another subspace z. These projected representations are indicated by `z_θ` and `z’_ϵ` in the image below.\n- Since the target network is the slow moving average of the online network, the online representations should be predictive of the target representations, i.e. `z_θ` should predict `z’_ϵ` and hence another predictor(`q_θ`) is put on top of `z_θ`.\n- Contrastive loss is reduced between <`q_θ(z_θ)`, `z’_ϵ`>.\n\n\n**Implementation**\n\n**Augmentations**\n\nTo make oue implementation easy we use the following set of augmentations are used.\n\n```python\nfrom torchvision import transforms as tfms\nbyol_tfms = tfms.Compose([\n tfms.RandomResizedCrop(size=512, scale=(0.3, 1)),\n tfms.RandomHorizontalFlip(),\n tfms.ToPILImage(),\n tfms.RandomApply([\n tfms.ColorJitter(0.4, 0.4, 0.4, 0.1)\n ], p=0.8),\n tfms.RandomGrayscale(p=0.2),\n tfms.ToTensor()\n])\n```\n\nWe then set up a pipeline to run our models through for training with contrastive learning. \nBelow PyTorch snippet implements the an encoder based BYOL network, but it could also be used in conjunction with any arbitrary encoder network such as VGG, InceptionNet, etc. without any significant change.\n\n**BYOL Module**\n\n\n```python\nclass BYOL(nn.Module):\n def __init__(self, backbone=None,base_target_ema=0.996,**kwargs):\n super().__init__()\n self.base_ema = base_target_ema \n if backbone is None:\n backbone = models.resnet50(pretrained=False)\n backbone.output_dim = backbone.fc.in_features\n backbone.fc = torch.nn.Identity()\n projector = MLPHead(in_dim=backbone.output_dim) \n self.online_encoder = nn.Sequential(backbone, projector) \n self.target_encoder = copy.deepcopy(self.online_encoder)\n self.online_predictor = MLPHead(in_dim=256,hidden_size=1024, projection_size=256) \n\n @torch.no_grad()\n def update_moving_average(self, global_step, max_steps): \n tau = 1- ((1 - self.base_ema)* (cos(pi*global_step/max_steps)+1)/2) \n for online, target in zip(self.online_encoder.parameters(), self.target_encoder.parameters()):\n target.data = tau * target.data + (1 - tau) * online.data \n \n def forward(self,x1,x2): \n z1 = self.online_encoder(x1)\n z2 = self.online_encoder(x2) \n q1 = self.online_predictor(z1)\n q2 = self.online_predictor(z2) \n with torch.no_grad():\n z1_t = self.target_encoder(x1)\n z2_t = self.target_encoder(x2) \n loss = loss_fn(q1, q2, z1_t, z2_t) \n return loss\n```\n\n\n**Training Loop**\n\nYou then can use a simple training loop to train your model.\n\n\n```python\nfor epoch in global_progress:\n model.train() \n \n for idx, (image, label) in enumerate(local_progress):\n image = image.to(device)\n aug_image = train_transform(image)\n \n model.zero_grad()\n loss = model.forward(image.to(device, non_blocking=True), aug_image.to(device, non_blocking=True)) \n loss.backward()\n \n optimizer.step()\n model.update_moving_average(epoch, epochs)\n \n scheduler.step() \n``` \n\n\n\n**Code:** You can find a good implementation in a Kaggle notebook of BYOL [here](https://www.kaggle.com/code/nikhilpandey360/contrastive-learning-using-byol)", "2079078": "Self-Supervised Deep Learning to Enhance Breast Cancer Detection on Screening Mammograph\nhttps://arxiv.org/pdf/2203.08812.pdf\n\n\n\n\n---\n\nfyi:\n\nA built in MIP (multiple instance pooling) network is facebook's PatchConvnet[1]\n\n\" We replace the final average pooling by an attention-based aggregation layer akin to a single transformer block, that weights how the patches are involved in the classification decision.\"\n\n[1] Augmenting Convolutional networks with attention-based aggregation \n[2] https://github.com/facebookresearch/deit/blob/main/README_patchconvnet.md\n\n\n",
"2076861": "Great thread! I also feel self-supervision is very much worth exploring in this competition.\n\nThe dataset is unbalanced, there are not that many examples in total and we are using models that have been pretrained on Imagenet, images that are vastly different from the DICOMs we get to work with in this competition.\n\nReally nice write-up of the available techniques!"
}
}