
\n5251_thumbnail.png
TMA images are centre cropped (eg. 3000 -> 2500) and resized to 768x768 pixels.
\nA single segmentation model is used for title selection. Segmentation is trained on thumbnail images and supplemental mask data. Tiles from thumbnails are used for mask generation. The location of the pixel with highest probability of being cancerous is selected on the WSI and a region of 1536x1536 pixels around it is cropped and resized to 768x768 pixels, which is then used to predict scores.
\nNo external data was used.
\nPrediction with low scores (< 0.05) can be labelled as Others. Another method is to predict bottom 5 or 10 percentile scores as Others.
\nSubmission notebook
\nSubmission notebook - single model
\nGithub
\n5251_thumbnail.png
When two or more slices are added side by side as in the above image, the height of the thumbnail becomes smaller, making it harder for the model to predict accurately. For such thumbnails, new thumbnails using WSI are generated - this boosted my score significantly.
", "messages": [ { "id": 2588752, "postDate": "2024-01-05T17:46:46.410Z", "content": "TMA images are centre cropped (eg. 3000 -> 2500) and resized to 768x768 pixels.
\nA single segmentation model is used for title selection. Segmentation is trained on thumbnail images and supplemental mask data. Tiles from thumbnails are used for mask generation. The location of the pixel with highest probability of being cancerous is selected on the WSI and a region of 1536x1536 pixels around it is cropped and resized to 768x768 pixels, which is then used to predict scores.
\nNo external data was used.
\nPrediction with low scores (< 0.05) can be labelled as Others. Another method is to predict bottom 5 or 10 percentile scores as Others.
\nSubmission notebook
\nSubmission notebook - single model
\nGithub
\n5251_thumbnail.png
When two or more slices are added side by side as in the above image, the height of the thumbnail becomes smaller, making it harder for the model to predict accurately. For such thumbnails, new thumbnails using WSI are generated - this boosted my score significantly.
", "rawMarkdown": "## TMA\nTMA images are centre cropped (eg. 3000 -> 2500) and resized to 768x768 pixels.\n\n## WSI\nA single segmentation model is used for title selection. Segmentation is trained on thumbnail images and supplemental mask data. Tiles from thumbnails are used for mask generation. The location of the pixel with highest probability of being cancerous is selected on the WSI and a region of 1536x1536 pixels around it is cropped and resized to 768x768 pixels, which is then used to predict scores.\n\n## Models\n- A total of 16 models based on Convnext, Hornet, Efficientnetv1, Efficientnetv2 are used. Instead of softmax,\nsigmoid activation is used for predicting scores.\n- Models are trained on 5 labels + non-cancerous label (using supplemental mask data).\n- Loss used: Binary crossentropy.\n- Augmentations used: Stain augmentation, scaling, rotation, flipud, fliplr, random contrast, random brightness, and random hue (thought it might work as stain augmentation).\n- Median averaging is used for generating score.\n- A single classifier model along with the segmentation model gives a score of 0.49, 0.55 for public and private leaderboard respectively. \n- Models are divided among the two gpus (T4 x 2) for memory efficiency.\n\n## External Data\nNo external data was used.\n\n## Outliers\nPrediction with low scores (< 0.05) can be labelled as *Others*. Another method is to predict bottom 5 or 10 percentile scores as *Others*.\n\n## Code\n[Submission notebook](https://www.kaggle.com/code/mmelahi/ubc-ocean-final-inference/notebook)\n[Submission notebook - single model](https://www.kaggle.com/mmelahi/ubc-ocean-final-single-model-inference)\n[Github](https://github.com/ManzoorElahi/UBC-Ovarian-Cancer-Subtype-Classification-and-Outlier-Detection)\n\n## Problematic thumbnail images\n\n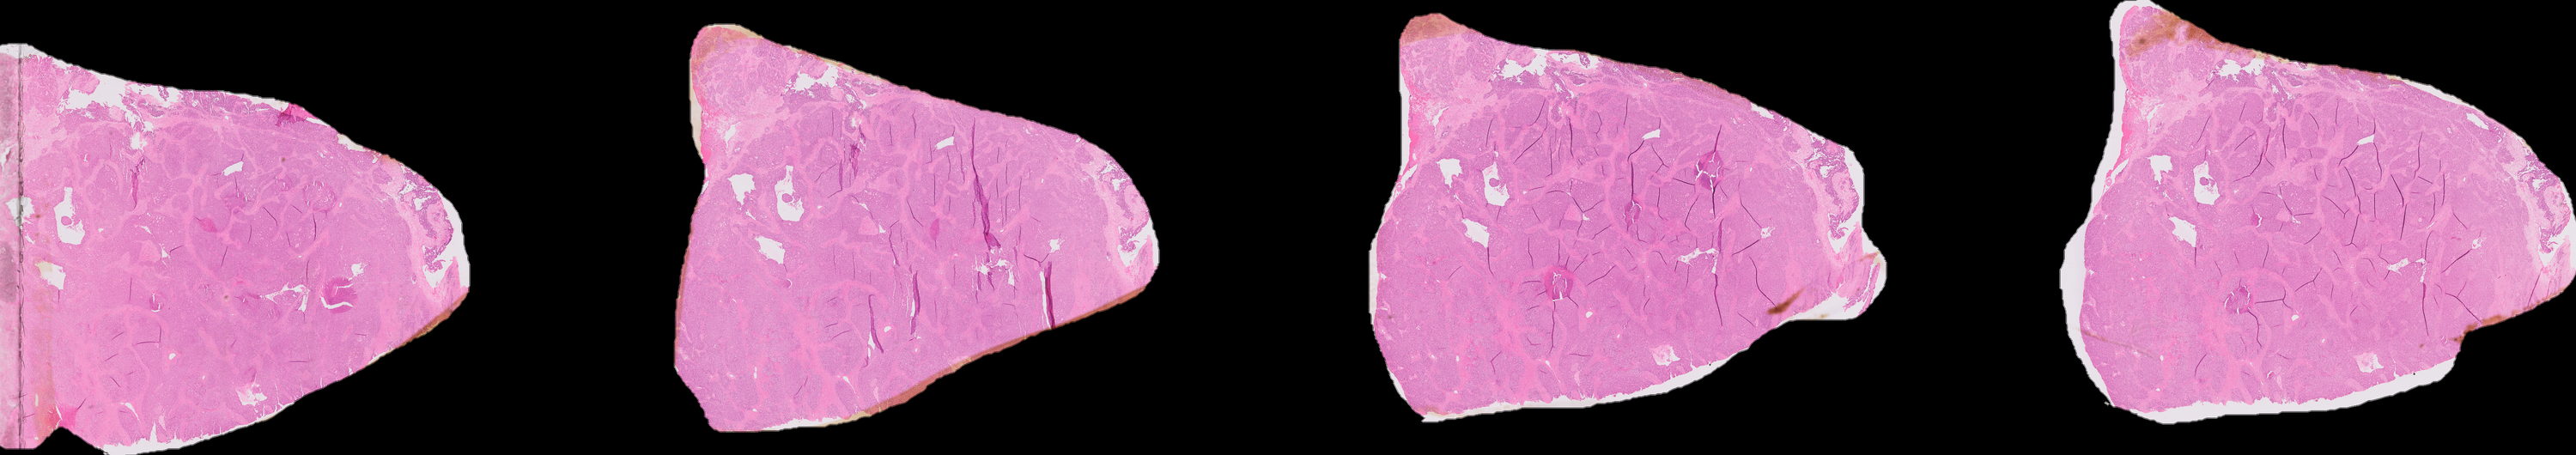\n**5251_thumbnail.png**\n\nWhen two or more slices are added side by side as in the above image, the height of the thumbnail becomes smaller, making it harder for the model to predict accurately. For such thumbnails, new thumbnails using WSI are generated - this boosted my score significantly. ", "votes": 16 }, { "id": 2589036, "postDate": "2024-01-06T02:10:18.610Z", "content": "Congratulations @mmelahi , reaching such a score without MIL, just a simple median operation is crazy.
", "rawMarkdown": "Congratulations @mmelahi , reaching such a score without MIL, just a simple median operation is crazy. ", "votes": 1, "replies": [ { "id": 2589039, "postDate": "2024-01-06T02:26:06.393Z", "content": "Before the competition ended, I thought there was a risk of overfitting with MIL, so using a simple aggregation strategy from patch to slide might be more robust. But I simply tried voting, and the score was very poor. I'm happy to see that you implemented this successfully.
", "rawMarkdown": "Before the competition ended, I thought there was a risk of overfitting with MIL, so using a simple aggregation strategy from patch to slide might be more robust. But I simply tried voting, and the score was very poor. I'm happy to see that you implemented this successfully." } ] }, { "id": 2589361, "postDate": "2024-01-06T10:26:36.977Z", "content": "Congratulations @mmelahi
", "rawMarkdown": "Congratulations @mmelahi " }, { "id": 2588785, "postDate": "2024-01-05T18:16:30.843Z", "content": "Simple and nice, congratulations. I didn't think that thumbnails could help.
", "rawMarkdown": "Simple and nice, congratulations. I didn't think that thumbnails could help." } ], "comments": [ { "id": 2589036, "author_name": "ForcewithMe", "author_url": "", "post_date": "2024-01-06T02:10:18.610000", "content": "Congratulations @mmelahi , reaching such a score without MIL, just a simple median operation is crazy.
", "votes": 1, "replies": [ { "id": 2589039, "author_name": "ForcewithMe", "author_url": "", "post_date": "2024-01-06T02:26:06.393000", "content": "Before the competition ended, I thought there was a risk of overfitting with MIL, so using a simple aggregation strategy from patch to slide might be more robust. But I simply tried voting, and the score was very poor. I'm happy to see that you implemented this successfully.
", "votes": 0, "replies": [] } ] }, { "id": 2589361, "author_name": "Huma Perveen", "author_url": "", "post_date": "2024-01-06T10:26:36.977000", "content": "Congratulations @mmelahi
", "votes": 0, "replies": [] }, { "id": 2588785, "author_name": "MPWARE", "author_url": "", "post_date": "2024-01-05T18:16:30.843000", "content": "Simple and nice, congratulations. I didn't think that thumbnails could help.
", "votes": 0, "replies": [] } ], "raw_markdown_by_id": { "2588752": "## TMA\nTMA images are centre cropped (eg. 3000 -> 2500) and resized to 768x768 pixels.\n\n## WSI\nA single segmentation model is used for title selection. Segmentation is trained on thumbnail images and supplemental mask data. Tiles from thumbnails are used for mask generation. The location of the pixel with highest probability of being cancerous is selected on the WSI and a region of 1536x1536 pixels around it is cropped and resized to 768x768 pixels, which is then used to predict scores.\n\n## Models\n- A total of 16 models based on Convnext, Hornet, Efficientnetv1, Efficientnetv2 are used. Instead of softmax,\nsigmoid activation is used for predicting scores.\n- Models are trained on 5 labels + non-cancerous label (using supplemental mask data).\n- Loss used: Binary crossentropy.\n- Augmentations used: Stain augmentation, scaling, rotation, flipud, fliplr, random contrast, random brightness, and random hue (thought it might work as stain augmentation).\n- Median averaging is used for generating score.\n- A single classifier model along with the segmentation model gives a score of 0.49, 0.55 for public and private leaderboard respectively. \n- Models are divided among the two gpus (T4 x 2) for memory efficiency.\n\n## External Data\nNo external data was used.\n\n## Outliers\nPrediction with low scores (< 0.05) can be labelled as *Others*. Another method is to predict bottom 5 or 10 percentile scores as *Others*.\n\n## Code\n[Submission notebook](https://www.kaggle.com/code/mmelahi/ubc-ocean-final-inference/notebook)\n[Submission notebook - single model](https://www.kaggle.com/mmelahi/ubc-ocean-final-single-model-inference)\n[Github](https://github.com/ManzoorElahi/UBC-Ovarian-Cancer-Subtype-Classification-and-Outlier-Detection)\n\n## Problematic thumbnail images\n\n\n**5251_thumbnail.png**\n\nWhen two or more slices are added side by side as in the above image, the height of the thumbnail becomes smaller, making it harder for the model to predict accurately. For such thumbnails, new thumbnails using WSI are generated - this boosted my score significantly. ", "2589036": "Congratulations @mmelahi , reaching such a score without MIL, just a simple median operation is crazy. ", "2589361": "Congratulations @mmelahi ", "2588785": "Simple and nice, congratulations. I didn't think that thumbnails could help." } }